Services · Index architecture

Deciding what deserves to be indexed at all

Deciding what deserves to be indexed at all. On a large catalog, the most valuable technical decision is usually subtraction rather than addition: fewer, stronger URLs that Googlebot can reach quickly and that a searcher would actually want to land on.

Index architecture

More indexed pages is not the goal

A site with two hundred thousand indexed URLs and eight thousand that anyone would want to land on is not a strong site. It is a site spreading its crawl and its internal links across pages that will never rank and never convert.

Pagination that goes forty pages deep, tag pages generated automatically, near-identical location pages, filter combinations nobody searches for. Each was cheap to create and each carries an ongoing cost in crawl requests and diluted signals.

Deciding what should not be indexed is unglamorous work. The indexed-page count goes down before traffic goes up, which is why it tends to be postponed, and why it is so often the highest-leverage work available.

What the work is

Index architecture, in four parts.

01

Canonical and pagination policy

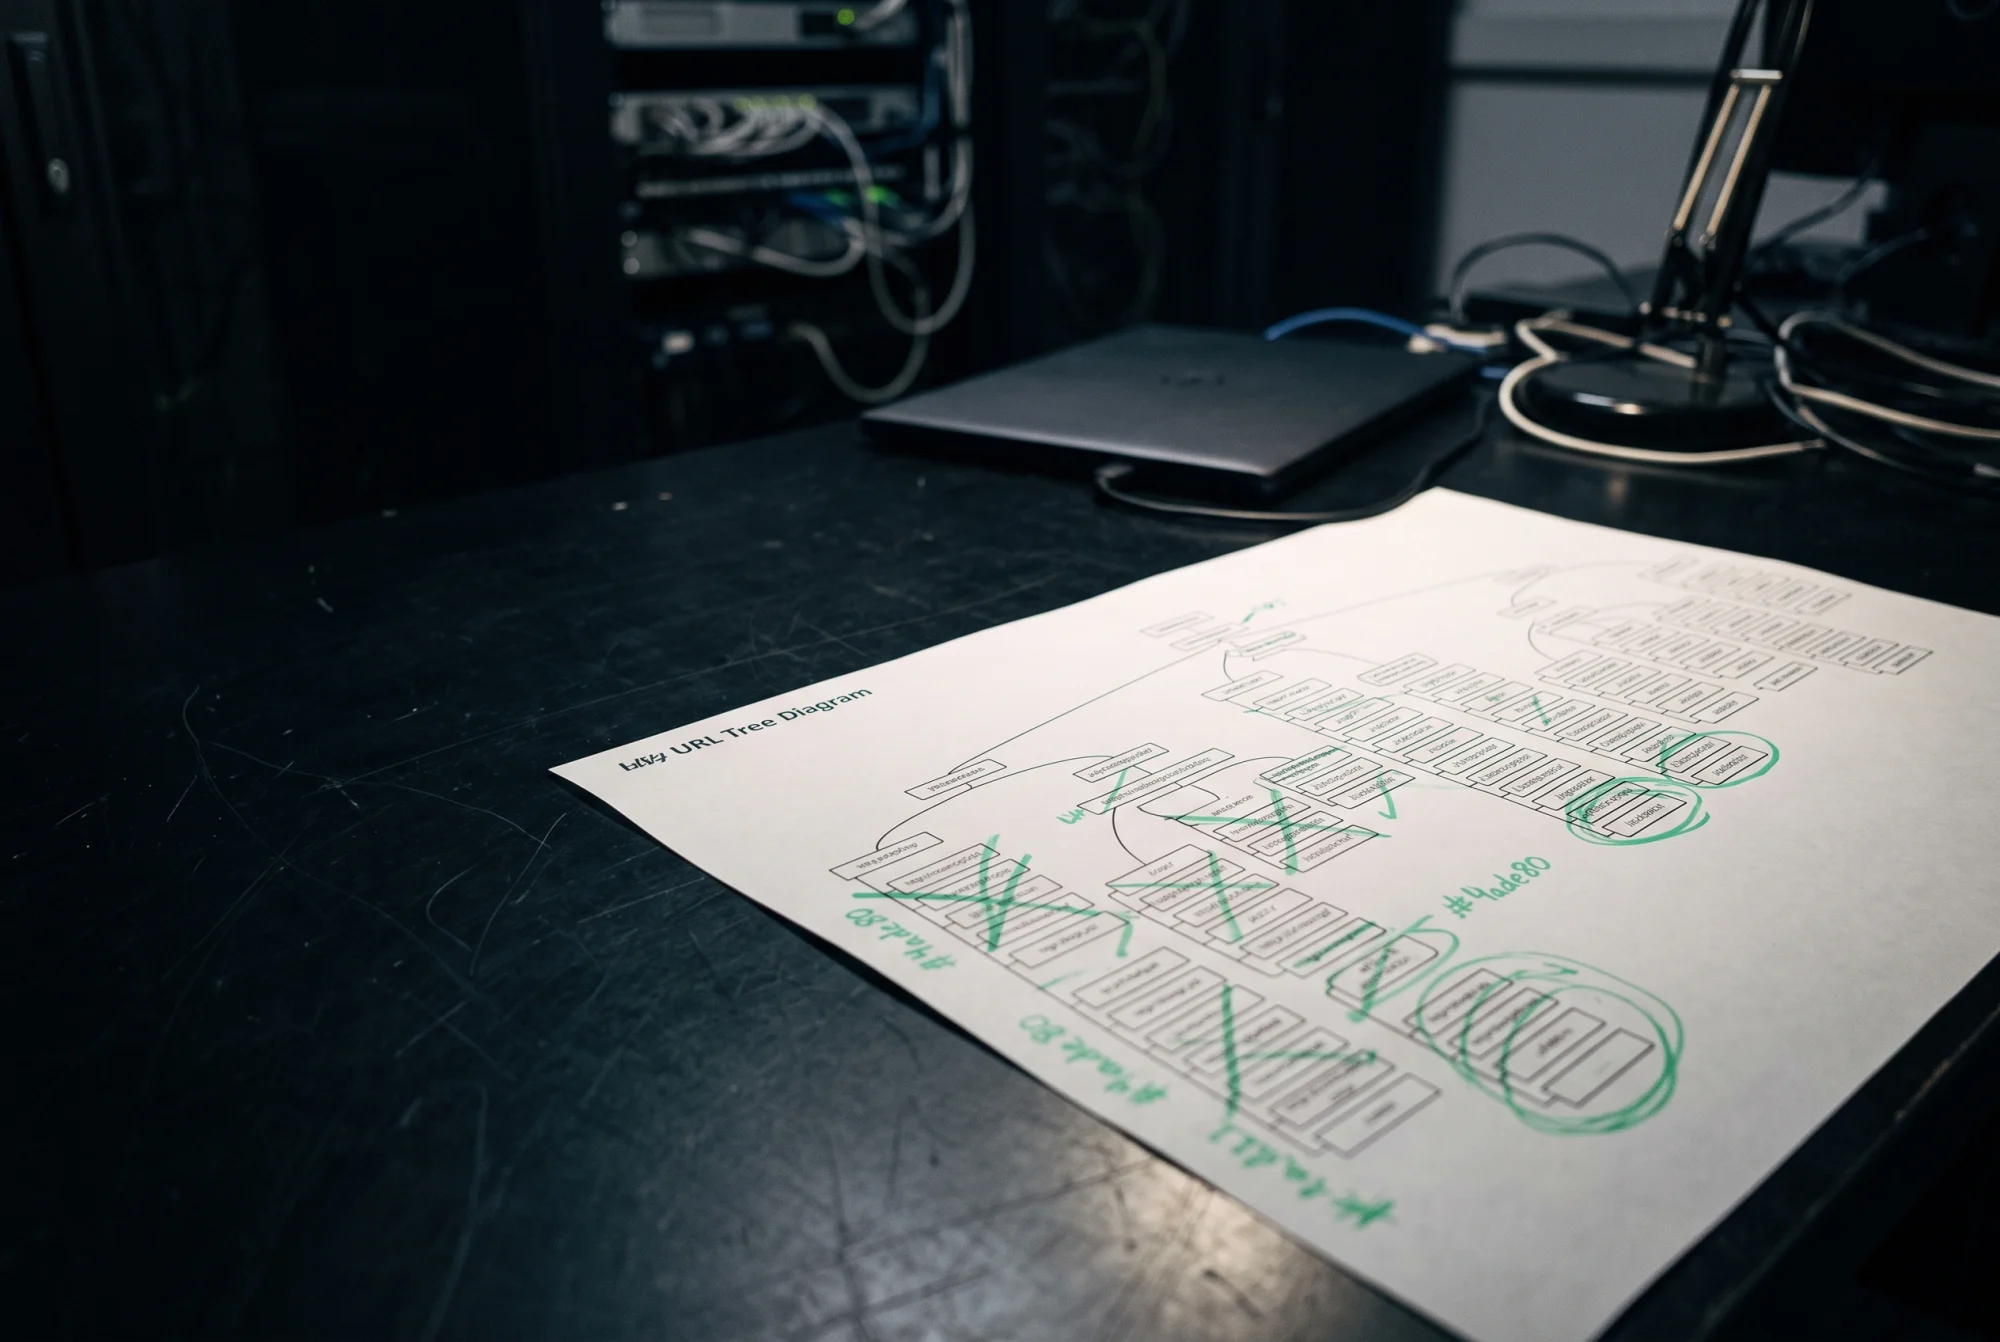
One documented rule for how canonical URLs are chosen and how paginated lists are handled, applied the same way on every template instead of decided feature by feature by whoever built it. We check the rule against the crawl, list every template that breaks it, and note where Google has chosen a different canonical from the one you declared, because that disagreement is usually a symptom of something else.
02

Internal link analysis

We build the internal link graph from the crawl and measure how links, and the authority they carry, flow through it. Commercially important pages are often five or six clicks from the home page while an auto-generated tag archive sits in the main navigation. The output is a short list of pages to promote, pages to demote, and the template changes that do it at scale.

03

Segmented XML sitemaps

Sitemaps split by template and by freshness, so indexing can be measured per segment in Search Console. A single sitemap file set with two hundred thousand URLs tells you nothing when coverage drops; ten segments tell you which template dropped and roughly when. We specify the segments and the update rules, and your developers generate them.

04

Migration and redirect mapping

Where structure has to change, every legacy URL is mapped to its new destination before anything moves, including old redirects that would otherwise turn into chains. After launch we check the map against a fresh crawl and, on Retainer and Embedded, against the logs, rather than assuming it is correct. Migration planning support is part of the Embedded plan.

What you receive
  • A written indexing policy covering every template on the site
  • An internal link analysis naming the pages that deserve promotion
  • A sitemap specification, with coverage tracked per segment in Search Console
  • A complete redirect map, checked after launch, where restructuring is required
Timeline

The canonical, pagination and internal-link review is part of the two-week crawl audit. The written policy and sitemap specification follow in the first month of a monthly plan. Changes are then staged template by template, a few weeks apart, so each one can be measured on its own.

Who this is for

Online stores, marketplaces, classifieds and publishers where the number of URLs has outgrown the structure behind them, and any site planning a replatform, a change of URL structure or a merge of two domains.

What it costs

Priced on the pricing page — no quote needed to find out.

Questions

About this service.

Will removing pages from the index reduce our traffic?
Pages that bring no search traffic cannot lose it. We confirm that in Search Console before anything is removed, stage the change by template, and watch coverage and the logs at each step. If a segment turns out to matter, it shows up before the next one moves.
Noindex or robots.txt?
They solve different problems and are often used as if they were the same, which is how sites end up with pages that are blocked from crawling and therefore cannot be dropped from the index. Noindex keeps a page out of the index; robots.txt keeps it out of the crawl. We decide case by case and document the reasoning.
How do you check that a fix worked?
A re-crawl compared with the previous one and, where we have logs, a log comparison. If a change cannot be measured in the crawl, the logs or Search Console coverage, we do not count it as done.

All questions →

Start with a crawl audit.

$160, fixed price, two weeks. Findings ranked by impact with the evidence attached, and the fee credited against your first month if you continue.

Get in touch